<?xml version="1.0" encoding="utf-8"?><feed xmlns="http://www.w3.org/2005/Atom" ><generator uri="https://jekyllrb.com/" version="3.10.0">Jekyll</generator><link href="http://www.andywaite.com/feed.xml" rel="self" type="application/atom+xml" /><link href="http://www.andywaite.com/" rel="alternate" type="text/html" /><updated>2026-08-25T19:14:53+00:00</updated><id>http://www.andywaite.com/feed.xml</id><title type="html">Andy Waite</title><subtitle>Ruby and Rails Developer, Toronto
</subtitle><entry><title type="html">Using puma-dev with Conductor</title><link href="http://www.andywaite.com/2026/08/25/using-puma-dev-with-conductor.html" rel="alternate" type="text/html" title="Using puma-dev with Conductor" /><published>2026-08-25T00:00:00+00:00</published><updated>2026-08-25T00:00:00+00:00</updated><id>http://www.andywaite.com/2026/08/25/using-puma-dev-with-conductor</id><content type="html" xml:base="http://www.andywaite.com/2026/08/25/using-puma-dev-with-conductor.html"><![CDATA[<p><a href="https://github.com/puma/puma-dev">puma-dev</a> is a useful tool for Rails developers. It’s a successor to <a href="https://github.com/basecamp/pow">pow</a>, an older tool by Basecamp.</p>

<p>puma-dev makes it easy to switch between working on multiple Rails apps in a local environment, without dealing with port conflicts. It also spins down idle apps to save resources.</p>

<p>Let’s say you’re working on an app in <code class="language-plaintext highlighter-rouge">~/src/myapp</code>. If you run <code class="language-plaintext highlighter-rouge">puma-dev link</code>, it will create a new symlink in <code class="language-plaintext highlighter-rouge">~/.puma-dev/</code>. You can then access your app on your local machine at <code class="language-plaintext highlighter-rouge">https://myapp.test</code>, without having to manually start a Rails instance.</p>

<p>With the emergence of AI agents, it’s becoming more common to be working on multiple features concurrently in isolated workspaces by using Git worktrees.</p>

<p>In <a href="https://conductor.build">Conductor</a> you can specify <a href="https://www.conductor.build/docs/reference/scripts">scripts</a> to run when setting up a new workspace or archiving an existing one. We can make use of these to set up puma-dev automatically.</p>

<p>Conductor assigns random names to workspaces (from a list of city names). For the hostname, I prefer to prefix the workspace name with my repo name, e.g. <code class="language-plaintext highlighter-rouge">https://myapp-toronto.test</code>.</p>

<p>When a workspace is longer needed, e.g. the feature has been merged, the workspace can be archived, and the symlink will be removed from <code class="language-plaintext highlighter-rouge">~/.puma-dev/</code>.</p>

<p>Here are the scripts that I’m using:</p>

<h2 id="binconductor-setup"><code class="language-plaintext highlighter-rouge">bin/conductor-setup</code></h2>

<div class="language-ruby highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="c1">#!/usr/bin/env ruby</span>
<span class="n">workspace_path</span> <span class="o">=</span> <span class="no">ENV</span><span class="p">.</span><span class="nf">fetch</span><span class="p">(</span><span class="s2">"CONDUCTOR_WORKSPACE_PATH"</span><span class="p">)</span>
<span class="n">project</span> <span class="o">=</span> <span class="no">File</span><span class="p">.</span><span class="nf">basename</span><span class="p">(</span><span class="no">File</span><span class="p">.</span><span class="nf">dirname</span><span class="p">(</span><span class="n">workspace_path</span><span class="p">))</span>
<span class="nb">name</span> <span class="o">=</span> <span class="s2">"</span><span class="si">#{</span><span class="n">project</span><span class="si">}</span><span class="s2">-</span><span class="si">#{</span><span class="no">File</span><span class="p">.</span><span class="nf">basename</span><span class="p">(</span><span class="n">workspace_path</span><span class="p">)</span><span class="si">}</span><span class="s2">"</span>
<span class="nb">system</span><span class="p">(</span><span class="s2">"puma-dev link -n </span><span class="si">#{</span><span class="nb">name</span><span class="si">}</span><span class="s2">"</span><span class="p">)</span> <span class="n">or</span> <span class="nb">abort</span> <span class="s2">"puma-dev link failed"</span>
<span class="nb">puts</span> <span class="s2">"puma-dev link succeeded: https://</span><span class="si">#{</span><span class="nb">name</span><span class="si">}</span><span class="s2">.test"</span>
</code></pre></div></div>

<h2 id="binconductor-archive"><code class="language-plaintext highlighter-rouge">bin/conductor-archive</code></h2>

<div class="language-ruby highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="c1">#!/usr/bin/env ruby</span>
<span class="n">workspace_path</span> <span class="o">=</span> <span class="no">ENV</span><span class="p">.</span><span class="nf">fetch</span><span class="p">(</span><span class="s2">"CONDUCTOR_WORKSPACE_PATH"</span><span class="p">)</span>
<span class="n">project</span> <span class="o">=</span> <span class="no">File</span><span class="p">.</span><span class="nf">basename</span><span class="p">(</span><span class="no">File</span><span class="p">.</span><span class="nf">dirname</span><span class="p">(</span><span class="n">workspace_path</span><span class="p">))</span>
<span class="nb">name</span> <span class="o">=</span> <span class="s2">"</span><span class="si">#{</span><span class="n">project</span><span class="si">}</span><span class="s2">-</span><span class="si">#{</span><span class="no">File</span><span class="p">.</span><span class="nf">basename</span><span class="p">(</span><span class="n">workspace_path</span><span class="p">)</span><span class="si">}</span><span class="s2">"</span>
<span class="n">symlink</span> <span class="o">=</span> <span class="no">File</span><span class="p">.</span><span class="nf">expand_path</span><span class="p">(</span><span class="s2">"~/.puma-dev/</span><span class="si">#{</span><span class="nb">name</span><span class="si">}</span><span class="s2">"</span><span class="p">)</span>
<span class="no">File</span><span class="p">.</span><span class="nf">delete</span><span class="p">(</span><span class="n">symlink</span><span class="p">)</span>
</code></pre></div></div>

<p>You’ll also need to make each script executable using <code class="language-plaintext highlighter-rouge">chmod +x</code>.</p>

<p>To learn more about using Conductor with Rails, check out:</p>
<ul>
  <li><a href="https://afomera.dev/posts/2026-02-03-using-conductor-with-ruby-on-rails">Using Conductor.build with Ruby on Rails</a> by Andrea Fomera.</li>
  <li><a href="https://www.johnnunemaker.com/conducting-rails/">Conducting Rails</a> by John Nunemaker.</li>
</ul>]]></content><author><name></name></author><summary type="html"><![CDATA[puma-dev is a useful tool for Rails developers. It’s a successor to pow, an older tool by Basecamp.]]></summary></entry><entry><title type="html">Using hk for git pre-commit hooks in Ruby and Rails projects</title><link href="http://www.andywaite.com/2026/08/14/hk-git-pre-commit-hooks-ruby-rails.html" rel="alternate" type="text/html" title="Using hk for git pre-commit hooks in Ruby and Rails projects" /><published>2026-08-14T00:00:00+00:00</published><updated>2026-08-14T00:00:00+00:00</updated><id>http://www.andywaite.com/2026/08/14/hk-git-pre-commit-hooks-ruby-rails</id><content type="html" xml:base="http://www.andywaite.com/2026/08/14/hk-git-pre-commit-hooks-ruby-rails.html"><![CDATA[<p><a href="https://www.reddit.com/r/ruby/comments/1vo9mg3/using_hk_for_git_precommit_hooks_in_ruby_and/" target="_blank" rel="noopener">Discuss this post on Reddit</a></p>

<h2 id="introduction">Introduction</h2>

<p>In this post I’ll briefly explain what git hooks are, introduce <a href="https://hk.jdx.dev"><code class="language-plaintext highlighter-rouge">hk</code></a>, and show some practical examples of using it with Ruby and Rails projects.</p>

<h2 id="git-hooks">Git hooks</h2>

<p>Git hooks are shell scripts which run automatically in response to particular events. These are usually written to a hidden <code class="language-plaintext highlighter-rouge">.git/hooks</code> directory, either per project, or globally in your home directory.</p>

<p>The most commonly used kind of Git hook is a <code class="language-plaintext highlighter-rouge">pre-commit</code> hook, typically used for linting and formatting.</p>

<p>While you can write hooks by hand, people typically make use of hook manager tools. These usually provide higher-level abstractions, or make it easier to share hooks within a team, and keep them up to date. Common tools include:</p>

<ul>
  <li><a href="https://github.com/typicode/husky">Husky</a> (written in JavaScript) - popular in the Node/JS world</li>
  <li><a href="https://pre-commit.com">pre-commit</a> (written in Python)</li>
  <li><a href="https://github.com/sds/overcommit">Overcommit</a> (written in Ruby)</li>
  <li><a href="https://github.com/evilmartians/lefthook">Lefthook</a> (written in Go) - by Evil Martians, who are well-known in the Ruby world</li>
</ul>

<h2 id="other-approaches">Other approaches</h2>

<p>Although git hooks have been around for a long time, I have found that they are not so commonly used. Instead, people would usually rely on their editor for linting, and make use of format-on-save, for example with <a href="https://github.com/Shopify/ruby-lsp">Ruby LSP</a>.</p>

<p>Now that more and more code is being written by agents, there is often no editor tooling involved so that approach fails. You could use a prompt (e.g. in <code class="language-plaintext highlighter-rouge">CLAUDE.md</code>) to make your agent aware of your linting/formatting tools, but this is not ideal:</p>

<ul>
  <li>It’s slow. The latency as the agent goes back and forth with the linting/formatting tools is a drag.</li>
  <li>It’s a waste of tokens and context.</li>
  <li>The agent behaviour is non-deterministic, so even if it <em>usually</em> runs the linting/formatting, it may occasionally neglect to.</li>
</ul>

<p>The one thing that we should aim for is to <strong>always</strong> catch linting/formatting issues before CI runs, to avoid wasteful cycles.</p>

<p>With hooks, we can have consistent and reliable linting and formatting for both human-authored and agent-authored code.</p>

<h2 id="introducing-hk">Introducing hk</h2>

<p><a href="https://hk.jdx.dev"><code class="language-plaintext highlighter-rouge">hk</code></a> is a project by <a href="https://jdx.dev">Jeff Dickey (<code class="language-plaintext highlighter-rouge">jdx</code>)</a> who is also the author of <a href="https://mise.jdx.dev"><code class="language-plaintext highlighter-rouge">mise</code></a>, a popular tool for managing development environments.</p>

<p>It was first <a href="https://github.com/jdx/mise/discussions/4434">announced</a> in February 2025. It fills a similar role to the tools listed above, but has some particular areas of emphasis:</p>

<ul>
  <li>Performance: It’s written in Rust and design so that tools can run concurrently, and knows to only run on modified files.</li>
  <li>Ease of configuration: It includes helpful defaults (“builtins”) for a wide variety of ecosystems.</li>
  <li>Low friction: It handles aspects such as re-staging of fixes, and doesn’t get in the way during git operations such as rebasing.</li>
</ul>

<h2 id="using-hk-with-ruby">Using hk with Ruby</h2>

<p><code class="language-plaintext highlighter-rouge">hk</code> includes builtins for many common Ruby tools:</p>

<ul>
  <li><a href="https://hk.jdx.dev/builtins.html#brakeman">brakeman</a></li>
  <li><a href="https://hk.jdx.dev/builtins.html#bundle-audit">bundle-audit</a></li>
  <li><a href="https://hk.jdx.dev/builtins.html#erb">erb</a></li>
  <li><a href="https://hk.jdx.dev/builtins.html#fasterer">fasterer</a></li>
  <li><a href="https://hk.jdx.dev/builtins.html#reek">reek</a></li>
  <li><a href="https://hk.jdx.dev/builtins.html#rubocop">rubocop</a></li>
  <li><a href="https://hk.jdx.dev/builtins.html#rubocop-server">rubocop-server</a></li>
  <li><a href="https://hk.jdx.dev/builtins.html#sorbet">sorbet</a></li>
  <li><a href="https://hk.jdx.dev/builtins.html#standard-rb">standard-rb</a></li>
</ul>

<p>(I <a href="https://github.com/jdx/hk/pull/995">contributed</a> <code class="language-plaintext highlighter-rouge">rubocop-server</code> to take advantage of RuboCop’s <a href="https://docs.rubocop.org/rubocop/latest/usage/server.html"><code class="language-plaintext highlighter-rouge">--server</code> mode</a>).</p>

<h2 id="getting-started">Getting Started</h2>

<p><code class="language-plaintext highlighter-rouge">hk</code> has good documentation on how to install it, so I won’t repeat the general steps here. Instead I’ll focus on Ruby and Rails.</p>

<p>Once installed, run <code class="language-plaintext highlighter-rouge">hk init</code> to create a default <code class="language-plaintext highlighter-rouge">hk.pkl</code> configuration for your project. This can later be committed to a project to allow others to make use of it.</p>

<p>The default <code class="language-plaintext highlighter-rouge">hk.pkl</code> has no active steps, so by default it does nothing.</p>

<p>(Sidenote: the configuration format used is <code class="language-plaintext highlighter-rouge">pkl</code>, pronounced ‘Pickle’, which I had never heard of before. I was surprised to discover that it’s an Apple <a href="https://pkl-lang.org">project</a>).</p>

<h2 id="adding-rubocop">Adding RuboCop</h2>

<p>We’ll start with RuboCop, since it’s so common in the Ruby world. Let’s add a step for it:</p>

<pre><code class="language-pkl">local linters = new Mapping&lt;String, Step&gt; {
["rubocop_server"] = Builtins.rubocop_server {
    prefix = "bundle exec"
}
</code></pre>

<p>Two things to note:</p>

<ul>
  <li>We are using <code class="language-plaintext highlighter-rouge">rubocop_server</code> instead of RuboCop, to avoid the startup overhead.</li>
  <li>We are prefixing the command to ensure it uses the RuboCop version from <code class="language-plaintext highlighter-rouge">Gemfile.lock</code>, rather than the latest installed gem version.</li>
</ul>

<p>Note that we don’t have to specify the RuboCop command or flags, or be aware of subtleties like the <a href="https://docs.rubocop.org/rubocop/latest/configuration/include_exclude.html"><code class="language-plaintext highlighter-rouge">--force-exclusion</code> flag</a>. It’s already defined as part of the builtin.</p>

<p>Let’s test it out by creating a very simple Ruby file without committing it.</p>

<div class="language-ruby highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="c1"># demo.rb</span>
<span class="nb">puts</span> <span class="s2">"hello world"</span>
</code></pre></div></div>
<p>Then run <code class="language-plaintext highlighter-rouge">bundle exec rubocop demo.rb</code></p>

<p>If you’re using the default RuboCop configuration, you should see two issues reported:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>demo.rb:1:1: C: [Correctable] Style/FrozenStringLiteralComment:
  Missing frozen string literal comment.
puts "hello world"
^
demo.rb:1:6: C: [Correctable] Style/StringLiterals:
  Prefer single-quoted strings when you don't need string interpolation or special symbols.
puts "hello world"
     ^^^^^^^^^^^^^
</code></pre></div></div>

<p>Now let’s try committing that file:</p>

<div class="language-sh highlighter-rouge"><div class="highlight"><pre class="highlight"><code>git add demo.rb
git commit <span class="nt">-m</span> <span class="s2">"Add demo.rb"</span>
</code></pre></div></div>

<p>You notice that one offense is fixed, but not the other. This is because <code class="language-plaintext highlighter-rouge">Style/FrozenStringLiteralComment</code> is considered an unsafe autocorrection in RuboCop, as it could <em>potentially</em> change the behaviour of the code.</p>

<p>Since the file is not considered valid, the commit is rejected. We need to manually fix the other offense by adding the <code class="language-plaintext highlighter-rouge"># frozen_string_literal: true</code> line, and then commit again.</p>

<p>If you were using a coding agent, you could let it handle this fix you. And depending on the model’s capabilities, it may be be able to check if <code class="language-plaintext highlighter-rouge"># frozen_string_literal: true</code> is actually safe or not in this case.</p>

<h2 id="adding-biome">Adding biome</h2>

<p>In the past I’ve used eslint alongside Prettier, but I’m now trying out <a href="https://github.com/biomejs/biome">biome</a>, a Rust-based linter/formatter which supports many frontend technologies including JavaScript, TypeScript, JSX, JSON, CSS and GraphQL.</p>

<p>First we need to add it to our <code class="language-plaintext highlighter-rouge">package.json</code>:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>npm install --save-dev --save-exact @biomejs/biome
</code></pre></div></div>

<p>Then it’s just a one line addition to our <code class="language-plaintext highlighter-rouge">hk.pkl</code> config:</p>

<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>local linters = new Mapping&lt;String, Step&gt; {
    // ...
    ["biome"] = Builtins.biome
}
</code></pre></div></div>

<h2 id="adding-herb">Adding Herb</h2>

<p>Let’s now look at how we could add support for a tool which isn’t currently natively supported by <code class="language-plaintext highlighter-rouge">hk</code>.</p>

<p><code class="language-plaintext highlighter-rouge">hk</code> has a builtin for <code class="language-plaintext highlighter-rouge">erb</code> linting, but there’s a better, modern linter and formatter for ERB files - <a href="https://herb-tools.dev">herb</a>. Its focus on performance makes it a great match for <code class="language-plaintext highlighter-rouge">hk</code>.</p>

<p>Although there is a <code class="language-plaintext highlighter-rouge">herb</code> Ruby gem, the tools we need, <code class="language-plaintext highlighter-rouge">herb-lint</code> and <code class="language-plaintext highlighter-rouge">herb-format</code>, are actually npm packages, so we’ll first add those to <code class="language-plaintext highlighter-rouge">package.json</code> as development dependencies:</p>
<div class="language-plaintext highlighter-rouge"><div class="highlight"><pre class="highlight"><code>npm install --save-dev --save-exact @herb-tools/formatter
npm install --save-dev --save-exact @herb-tools/linter
</code></pre></div></div>

<p>And as <code class="language-plaintext highlighter-rouge">hk</code> doesn’t have a builtin for <code class="language-plaintext highlighter-rouge">herb</code>, we’ll need to add some custom configuration in <code class="language-plaintext highlighter-rouge">hk.pkl</code>:</p>

<pre><code class="language-pkl">local linters = new Mapping&lt;String, Step&gt; {
    // ...
    
    ["herb_lint"] {
        glob = List("**/*.html.erb", "**/*.html", "**/*.rhtml", "**/*.turbo_stream.erb")
        exclude = List("node_modules/**/*")
        check = "node_modules/.bin/herb-lint "
        fix = "node_modules/.bin/herb-lint --fix "
    }
    
    ["herb_format"] {
        glob = List("**/*.html.erb", "**/*.html", "**/*.rhtml", "**/*.turbo_stream.erb")
        exclude = List("node_modules/**/*")
        check = "node_modules/.bin/herb-format --check "
        fix = "node_modules/.bin/herb-format "
    }
}
</code></pre>

<p>Note that we prefix the executable calls with <code class="language-plaintext highlighter-rouge">node_modules/.bin/</code> to prevent unintentionally falling back to globally installed versions, which could be different per machine.</p>

<p>With the above all set up, you’ll now have linting and formatting for almost every file in a typical Rails app.</p>

<h2 id="wrapping-up">Wrapping Up</h2>

<p>Along with <code class="language-plaintext highlighter-rouge">mise</code>, <code class="language-plaintext highlighter-rouge">hk</code> has become one the tools that I rely on every day as a developer. Whether your writing code by hand, or using an agent, it will catch linting and formatting issues quickly and effectively, allowing you to focus on the more interesting things.</p>]]></content><author><name></name></author><summary type="html"><![CDATA[Discuss this post on Reddit Introduction]]></summary></entry><entry><title type="html">Using Claude Code custom slash commands with Ruby</title><link href="http://www.andywaite.com/2025/07/07/using-claude-code-custom-slash-commands-with-ruby.html" rel="alternate" type="text/html" title="Using Claude Code custom slash commands with Ruby" /><published>2025-07-07T00:00:00+00:00</published><updated>2025-07-07T00:00:00+00:00</updated><id>http://www.andywaite.com/2025/07/07/using-claude-code-custom-slash-commands-with-ruby</id><content type="html" xml:base="http://www.andywaite.com/2025/07/07/using-claude-code-custom-slash-commands-with-ruby.html"><![CDATA[<p>For the past few weeks I’ve been using Claude Code extensively in my Ruby development workflow and find it incredibly powerful, especially since the launch of the Sonnet 4 model.</p>

<p>Anthropic recently added support for <a href="https://docs.anthropic.com/en/docs/claude-code/slash-commands#custom-slash-commands">custom slash commands</a>, allowing you to define commonly used prompts as reusable macros.</p>

<p>Based on my experience as a Ruby developer, I’ve created <a href="https://github.com/andyw8/claude_code_slash_commands/tree/main/commands">several custom commands</a> for typical Ruby project workflows, such as:</p>

<ul>
  <li>Configuring CI with GitHub Actions (including Ruby matrix builds)</li>
  <li>Adding RuboCop or Standard</li>
  <li>Bumping the Ruby version across gemspecs, Gemfiles, and CI configs</li>
  <li>Adding common Ruby gems with appropriate configuration</li>
</ul>

<p>Although Claude does a reasonable job for these with a zero-shot prompt, the custom commands allow for better adherence to modern best practices, which are often preferable over what the model was trained on.</p>

<p>Each command has been iteratively refined based on real-world usage across different Ruby projects. (I’ve found that using bullet-point checklists makes Claude more systematic about following instructions).</p>

<p>As these patterns may be valuable to the broader Ruby community, I’ve published a <a href="https://github.com/andyw8/claude_code_slash_commands">claude_code_slash_commands</a> gem (mostly written by Claude Code of course).</p>

<p>The gem provides a simple <code class="language-plaintext highlighter-rouge">install</code> command that copies the slash commands to your local <code class="language-plaintext highlighter-rouge">~/.claude/commands</code> directory. The commands are designed with Ruby development expertise in mind, incorporating common patterns and approaches.</p>

<p>If you have ideas for additional Ruby-focused slash commands, I’d love to see them! Feel free to open a PR on the <a href="https://github.com/andyw8/claude_code_slash_commands">repository</a> to contribute your own commands that could benefit the Ruby community.</p>]]></content><author><name></name></author><summary type="html"><![CDATA[For the past few weeks I’ve been using Claude Code extensively in my Ruby development workflow and find it incredibly powerful, especially since the launch of the Sonnet 4 model.]]></summary></entry><entry><title type="html">Setting up Zed with Ruby LSP</title><link href="http://www.andywaite.com/2025/03/31/setting-up-zed-with-ruby-lsp.html" rel="alternate" type="text/html" title="Setting up Zed with Ruby LSP" /><published>2025-03-31T00:00:00+00:00</published><updated>2025-03-31T00:00:00+00:00</updated><id>http://www.andywaite.com/2025/03/31/setting-up-zed-with-ruby-lsp</id><content type="html" xml:base="http://www.andywaite.com/2025/03/31/setting-up-zed-with-ruby-lsp.html"><![CDATA[<p>(Last updated: 2025-09-04)</p>

<p><a href="https://zed.dev">Zed</a> is a modern, high-performance code editor that’s gaining popularity. After several years of using VS Code, I’ve been trying it out for writing Ruby and I’ve been impressed. With recent rapid development in AI, Zed’s <a href="https://zed.dev/blog/zed-ai">close collaboration with Anthropic</a> makes it a strong contender to VS Code derived editors such as <a href="https://www.cursor.com">Cursor</a>.</p>

<p>In this post you’ll learn how to set up Ruby LSP with Zed, and how to troubleshoot if things aren’t working. I’ll also share some alternatives for features that aren’t currently available in Zed.</p>

<h1 id="setting-up-ruby-support">Setting up Ruby Support</h1>

<p>Zed’s Ruby support comes from the <a href="https://github.com/zed-extensions/ruby">official Ruby extension</a>, created by <a href="https://bsky.app/profile/vitallium.bsky.social">Vitaly Slobodin</a>. You can enable it through <code class="language-plaintext highlighter-rouge">zed: extensions</code>.</p>

<p>As with all Zed extensions, it is written in Rust. Its documentation can be found <a href="https://zed.dev/docs/languages/ruby">here</a>, as part of the official docs.</p>

<h1 id="configuring-ruby-lsp">Configuring Ruby LSP</h1>

<p>Zed has good built-in support for the <a href="https://microsoft.github.io/language-server-protocol/">Language Server Protocol</a>, meaning there’s a lot of tooling already available that can be used.</p>

<p>Zed defaults to using <a href="https://solargraph.org">Solargraph</a> as its language server for Ruby, but my preference is to use <a href="https://github.com/Shopify/ruby-lsp">Ruby LSP</a>, since I’m a <a href="https://github.com/Shopify/ruby-lsp/graphs/contributors">contributor</a>.</p>

<p>You’ll also be able to take advantage of Ruby LSP add-ons such as <a href="https://github.com/Shopify/ruby-lsp-rails">ruby-lsp-rails</a> and <a href="https://github.com/st0012/ruby-lsp-rspec">ruby-lsp-rspec</a>.</p>

<p>It can configured in Zed’s settings as follows:</p>

<div class="language-json highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="p">{</span><span class="w">
  </span><span class="nl">"languages"</span><span class="p">:</span><span class="w"> </span><span class="p">{</span><span class="w">
    </span><span class="nl">"Ruby"</span><span class="p">:</span><span class="w"> </span><span class="p">{</span><span class="w">
      </span><span class="nl">"language_servers"</span><span class="p">:</span><span class="w"> </span><span class="p">[</span><span class="s2">"ruby-lsp"</span><span class="p">]</span><span class="w">
    </span><span class="p">}</span><span class="w">
  </span><span class="p">}</span><span class="w">
</span><span class="p">}</span><span class="w">
</span></code></pre></div></div>

<p>(The docs suggest disabling each language server that you <em>don’t</em> want with <code class="language-plaintext highlighter-rouge">!</code>, and using <code class="language-plaintext highlighter-rouge">"..."</code> to enable the rest, but I find it simpler to just list the ones you <em>do</em> want).</p>

<p>Note: I’ve noticed that some configuration changes don’t seem to apply until you fully quit and reload the editor (<code class="language-plaintext highlighter-rouge">workspace: reload</code> isn’t enough), so you may need to do that in some situations.</p>

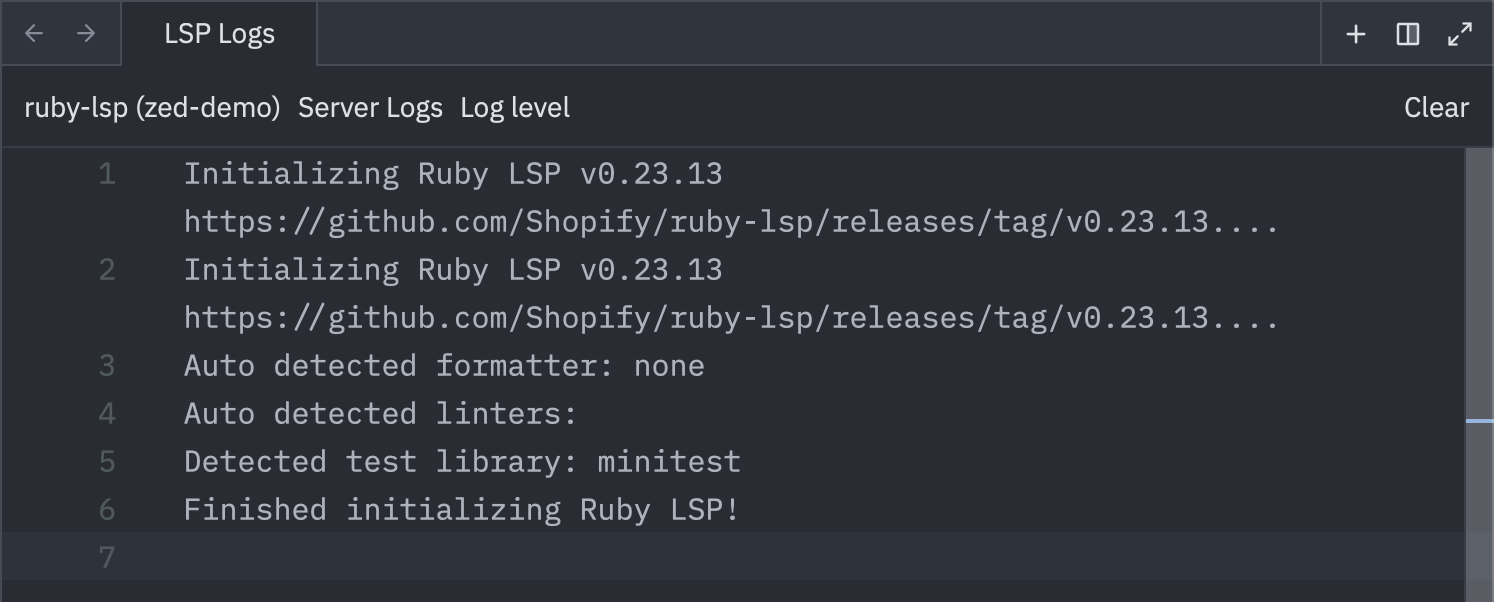
<p>To verify things are working, open a Ruby file, then choose <code class="language-plaintext highlighter-rouge">debug: open language server logs</code> from the command menu. The output should look something like this:</p>

<p><img src="/assets/images/zed-ruby-lsp-startup.png" alt="Ruby LSP startup" /></p>

<p>If there are multiple language servers running, then you’ll need to first select the <code class="language-plaintext highlighter-rouge">ruby-lsp</code> log from the menu at the top left.</p>

<p>If ever it seems that Ruby LSP is not running, this is the first place to check for errors.</p>

<h1 id="enabling-diagnostics-linting">Enabling Diagnostics (linting)</h1>

<p>Update: This section previously described a workaround for the lack of pull diagnostics support in Zed, but this has now been implemented and diagnostics are working.</p>

<h1 id="disable-ontypeformatting">Disable onTypeFormatting</h1>

<p>~There is <a href="https://github.com/Shopify/ruby-lsp/issues/2971">known issue</a> in Ruby LSP with cursor placement when trying to type a <code class="language-plaintext highlighter-rouge">|</code> for block arguments, so you may want to disable <code class="language-plaintext highlighter-rouge">onTypeFormatting</code> for now~</p>

<p>Update: This was <a href="https://github.com/zed-extensions/ruby/pull/142">changed</a> to be disabled by default in v0.13 of the extension.</p>

<h1 id="global-vs-local-settings">Global vs Local Settings</h1>

<p>So far I’ve shown settings as being added to the Zed’s global configuration.</p>

<p>If you only ever work on a single Ruby project, then it doesn’t really matter if you all your settings are global. But many of us work on codebases with different configurations, such as for linting and formatting, so having more granular control is often necessary.</p>

<p>You can add project-specific settings to <code class="language-plaintext highlighter-rouge">.zed/settings.json</code> in your project directory. These settings will be merged with the global settings, so normally you’ll only need a few lines of configuration.
For example, you might have some projects that use RuboCop but others that use Standard.</p>

<h1 id="running-tests">Running tests</h1>

<p>One very useful feature when using Ruby LSP in VS Code is <a href="https://shopify.github.io/ruby-lsp/#code-lens">Code Lens</a>, which adds a <code class="language-plaintext highlighter-rouge">Run in Terminal</code> link to each test, and shows the result in the integrated terminal.</p>

<p>This LSP feature is not supported by Zed, but we can use the powerful <a href="https://zed.dev/docs/tasks">Tasks</a> feature to do something similar.</p>

<p>For example, to add a task for running Rails tests, we can create a <code class="language-plaintext highlighter-rouge">.zed/tasks.json</code> file:</p>

<div class="language-json highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="p">[</span><span class="w">
  </span><span class="p">{</span><span class="w">
    </span><span class="nl">"label"</span><span class="p">:</span><span class="w"> </span><span class="s2">"test $ZED_RELATIVE_FILE:$ZED_ROW"</span><span class="p">,</span><span class="w">
    </span><span class="nl">"command"</span><span class="p">:</span><span class="w"> </span><span class="s2">"bundle exec rails"</span><span class="p">,</span><span class="w">
    </span><span class="nl">"args"</span><span class="p">:</span><span class="w"> </span><span class="p">[</span><span class="s2">"test"</span><span class="p">,</span><span class="w"> </span><span class="s2">"</span><span class="se">\"</span><span class="s2">$ZED_RELATIVE_FILE:$ZED_ROW</span><span class="se">\"</span><span class="s2">"</span><span class="p">],</span><span class="w">
    </span><span class="nl">"tags"</span><span class="p">:</span><span class="w"> </span><span class="p">[</span><span class="s2">"ruby-test"</span><span class="p">]</span><span class="w">
  </span><span class="p">}</span><span class="w">
</span><span class="p">]</span><span class="w">
</span></code></pre></div></div>

<p>The test can be run by clicking on the <code class="language-plaintext highlighter-rouge">▷</code> in the gutter, or with the Command-Shift-R keybinding.</p>

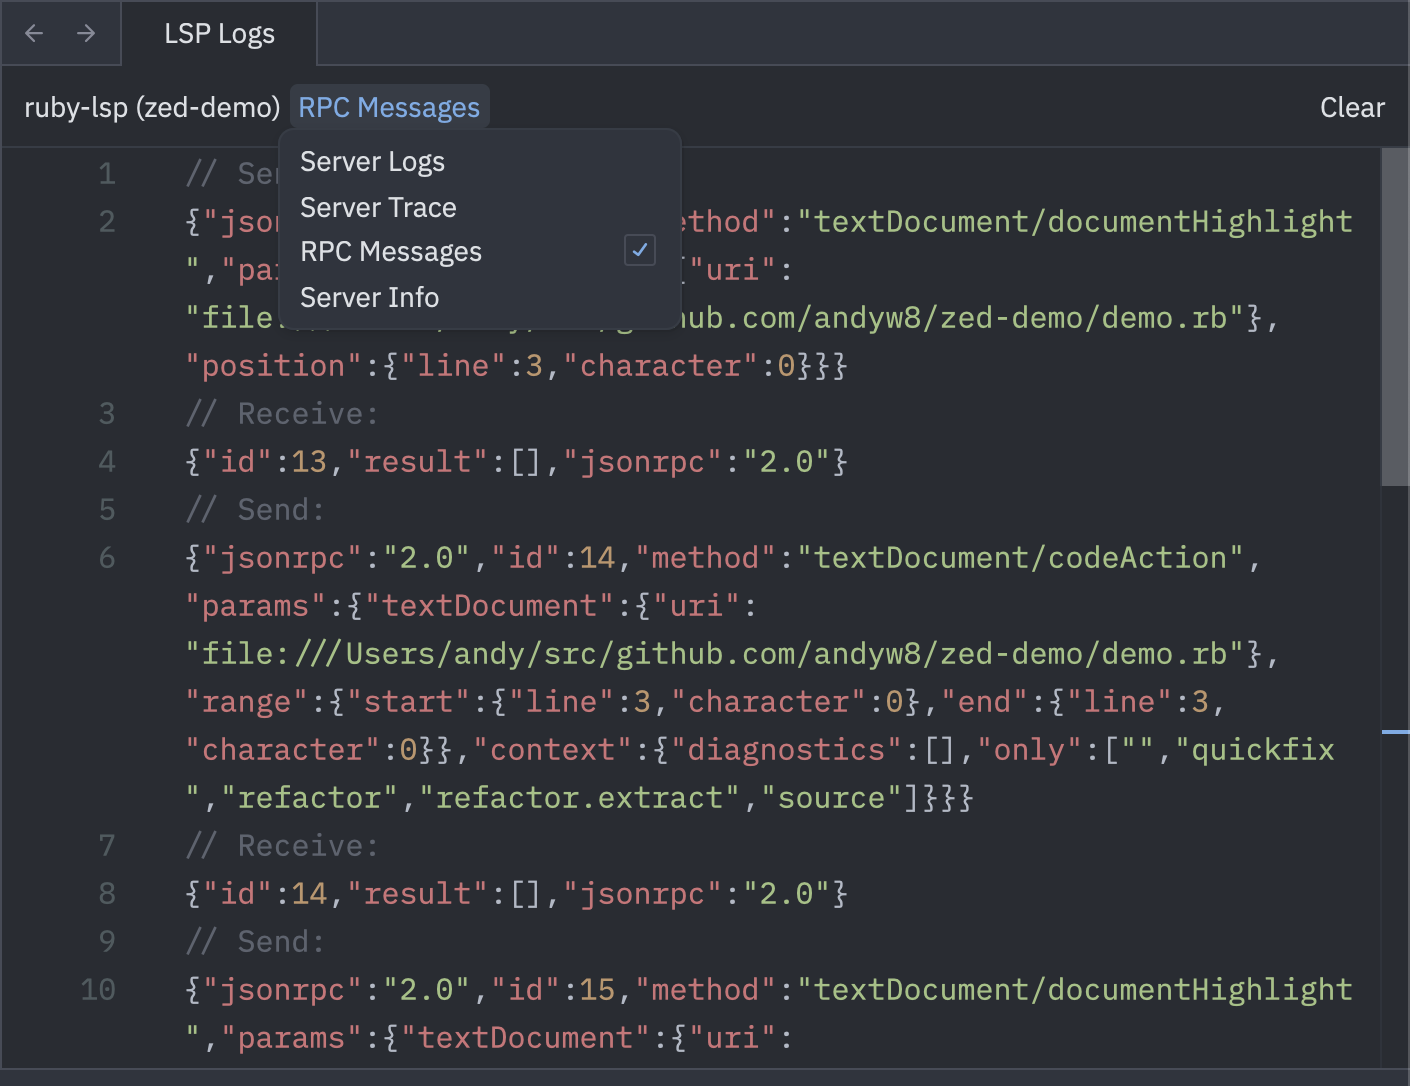
<h1 id="advanced-lsp-troubleshooting">Advanced LSP Troubleshooting</h1>

<p>It can sometimes be useful see the underlying requests and responses for the language server. In the <code class="language-plaintext highlighter-rouge">debug: language server logs</code> window, click the second menu, then enable <code class="language-plaintext highlighter-rouge">RPC Messages</code>:</p>

<p><img src="/assets/images/zed-lsp-rpc-logging.png" alt="Ruby LSP startup" /></p>

<h1 id="whats-missing">What’s Missing</h1>

<ul>
  <li>
    <p>If you’re coming from VS Code with Ruby LSP, you might notice some features are not available. There’s two main reasons behind this:</p>

    <ul>
      <li>
        <p>Some Ruby LSP features depends on custom behaviour in the VS Code extension. Those would need to be reimplemented for Zed within the Ruby extension.</p>
      </li>
      <li>
        <p>Some parts of the LSP specification are not yet implemented in Zed.
You can follow <a href="https://github.com/zed-industries/zed/issues/26916">this</a> Zed issue to learn more.</p>
      </li>
    </ul>
  </li>
  <li>
    <s>Changes aren't indexed until Zed is restarted.</s>
    <p>(<a href="https://github.com/Shopify/ruby-lsp/issues/3384">#3384</a>). This is now working.</p>
  </li>
  <li>
    <p>A debugger is in <a href="https://zed.dev/debugger">beta</a>, and there’s a <a href="https://github.com/zed-industries/zed/pull/30126">PR</a> open for supporting rdbg.</p>
  </li>
  <li>Zed supports <a href="https://zed.dev/docs/snippets">Snippets</a> but the Ruby extension doesn’t yet have any. I have a <a href="https://github.com/zed-extensions/ruby/pull/53">PR</a> in progress to add them.</li>
</ul>

<h1 id="other-useful-resources">Other Useful Resources</h1>

<ul>
  <li>For ERB linting, support for Herb has been <a href="https://github.com/zed-extensions/ruby/pull/110">merged</a> and should ship soon.</li>
  <li>For ERB formatting, <a href="https://zed.dev/docs/languages/ruby#erb-formatter">erb-formatter</a> works well.</li>
  <li>To toggle between a test and its implementation, try <a href="https://github.com/MoskitoHero/zed-test-toggle">zed-test-toggle</a>.</li>
  <li>For working with Hotwire, there is the <a href="https://github.com/vitallium/zed-stimulus">Zed Stimulus</a> extension.</li>
  <li>Support for Sorbet was previously available in a <a href="https://github.com/notchairmk/zed-sorbet">separate extension</a> but is now built-in as of v0.9.0 of the Ruby extension.</li>
</ul>]]></content><author><name></name></author><summary type="html"><![CDATA[(Last updated: 2025-09-04)]]></summary></entry><entry><title type="html">Extracting transcripts from Just Press Record</title><link href="http://www.andywaite.com/2024/12/08/extracting-transcripts-from-just-press-record.html" rel="alternate" type="text/html" title="Extracting transcripts from Just Press Record" /><published>2024-12-08T00:00:00+00:00</published><updated>2024-12-08T00:00:00+00:00</updated><id>http://www.andywaite.com/2024/12/08/extracting-transcripts-from-just-press-record</id><content type="html" xml:base="http://www.andywaite.com/2024/12/08/extracting-transcripts-from-just-press-record.html"><![CDATA[<p><a href="https://www.openplanetsoftware.com/just-press-record/">Just Press Record</a> is a nice little app for recording voice memos, available on macOS, iOS and watchOS.</p>

<p>It has the ability to automatically embed transcripts into the recordings. I wanted to extract these out to use with an automated workflow for OmniFocus, a task manager.</p>

<p>With a little bit of investigation, I could see the transcript was represented as a Base64 string contained in JSON. Here’s how to extract it:</p>

<div class="language-sh highlighter-rouge"><div class="highlight"><pre class="highlight"><code>strings recording.m4a | <span class="nb">tail</span> <span class="nt">-n</span> 1 | <span class="nb">sed</span> <span class="s1">'s/^[^\{]*//'</span> | jq <span class="nt">-r</span> <span class="s1">'._root.txscriptv2.tx._data'</span> | <span class="nb">base64</span> <span class="nt">--decode</span>
</code></pre></div></div>

<p>A brief explanation of how each command is used:</p>
<ul>
  <li><code class="language-plaintext highlighter-rouge">strings</code> to extract any text found within the file</li>
  <li><code class="language-plaintext highlighter-rouge">tail</code> to keep only the last line (the one with the JSON)</li>
  <li><code class="language-plaintext highlighter-rouge">sed</code> to discard the part of the line before the JSON structure</li>
  <li><a href="https://github.com/jqlang/jq"><code class="language-plaintext highlighter-rouge">jq</code></a> to extract the specific part of the JSON containing the encoded text (the <code class="language-plaintext highlighter-rouge">-r</code> flag removes the quotes).</li>
  <li><code class="language-plaintext highlighter-rouge">base64</code> to decode it</li>
</ul>]]></content><author><name></name></author><summary type="html"><![CDATA[Just Press Record is a nice little app for recording voice memos, available on macOS, iOS and watchOS.]]></summary></entry><entry><title type="html">An Introduction to the Ruby LSP Add-on System</title><link href="http://www.andywaite.com/2024/10/03/the-ruby-lsp-addon-system.html" rel="alternate" type="text/html" title="An Introduction to the Ruby LSP Add-on System" /><published>2024-10-03T00:00:00+00:00</published><updated>2024-10-03T00:00:00+00:00</updated><id>http://www.andywaite.com/2024/10/03/the-ruby-lsp-addon-system</id><content type="html" xml:base="http://www.andywaite.com/2024/10/03/the-ruby-lsp-addon-system.html"><![CDATA[<p>I wrote an <a href="https://railsatscale.com/2024-10-03-the-ruby-lsp-addon-system/">article</a>
 for <a href="https://twitter.com/ShopifyEng">Shopify Engineering</a>’s <a href="https://railsatscale.com">Rails at Scale</a> blog:</p>

<blockquote>
  <p>In this post we introduce the Ruby LSP add-on system. We’ll explain the problem it solves, discuss its architecture, showcase some example add-ons, and share our vision for a future addon ecosystem that enhances the Ruby development experience.</p>
</blockquote>

<p><a href="https://railsatscale.com/2024-10-03-the-ruby-lsp-addon-system/">https://railsatscale.com/2024-10-03-the-ruby-lsp-addon-system/</a></p>]]></content><author><name></name></author><summary type="html"><![CDATA[I wrote an article for Shopify Engineering’s Rails at Scale blog:]]></summary></entry><entry><title type="html">Adding Sorbet and Tapioca to a Jumpstart Pro app</title><link href="http://www.andywaite.com/2023/09/17/jumpstart-rails-pro-sorbet-tapioca.html" rel="alternate" type="text/html" title="Adding Sorbet and Tapioca to a Jumpstart Pro app" /><published>2023-09-17T00:00:00+00:00</published><updated>2023-09-17T00:00:00+00:00</updated><id>http://www.andywaite.com/2023/09/17/jumpstart-rails-pro-sorbet-tapioca</id><content type="html" xml:base="http://www.andywaite.com/2023/09/17/jumpstart-rails-pro-sorbet-tapioca.html"><![CDATA[<p>This post describes the process of setting up Sorbet and Tapioca for the <a href="https://jumpstartrails.com">Jumpstart Pro</a> Rails template.</p>

<p>Since Jumpstart Pro is a commercial product, I can’t share the full code, but if you’re a Jumpstart customer you can view the changes in <a href="https://github.com/andyw8/jumpstart-pro-rails/tree/andyw8/sorbet">this branch</a> of my fork. I recommend viewing it as individual commits to understand it step-by-step. The order may not exactly match the blog post, but the end result should be the same.</p>

<p>For this post, I’ll assume you are starting from a freshly generated Jumpstart app. If you have already built your app on top of Jumpstart then it may take some more effort but the overall approach is the same.</p>

<p>I’ll demonstrate the process in incremental steps, so your app can continue to be deployed while type information is still being added. This follows Sorbet’s philosophy of <a href="https://sorbet.org/docs/gradual">Gradual Typing</a>.</p>

<h2 id="preparation">Preparation</h2>

<p>Start by creating a <code class="language-plaintext highlighter-rouge">sorbet</code> branch for the Sorbet migration. This will be fairly short-lived, and only needed for the initial setup.</p>

<h2 id="setting-up-ci">Setting up CI</h2>

<p>Although Jumpstart Pro provides a GitHub Actions CI script, we’ll instead use <a href="https://www.andywaite.com/2022/04/15/reusable-github-actions-rails-workflow.html">setup-rails</a> since it will detect if Sorbet is in use and run additional checks. We’ll also enable the <code class="language-plaintext highlighter-rouge">standard</code> option, since that’s what Jumpstart uses instead of RuboCop.</p>

<div class="language-yml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="na">name</span><span class="pi">:</span> <span class="s">Verify</span>
<span class="na">on</span><span class="pi">:</span> <span class="pi">[</span><span class="nv">push</span><span class="pi">,</span> <span class="nv">pull_request</span><span class="pi">]</span>

<span class="na">jobs</span><span class="pi">:</span>
  <span class="na">verify</span><span class="pi">:</span>
    <span class="na">uses</span><span class="pi">:</span> <span class="s">setup-rails/setup-rails/.github/workflows/verify.yml@main</span>
    <span class="na">with</span><span class="pi">:</span>
      <span class="na">run-before-tests</span><span class="pi">:</span> <span class="s">sudo apt-get install -y -qq libvips</span>
      <span class="na">standard</span><span class="pi">:</span> <span class="no">true</span>
</code></pre></div></div>

<p>(I also had to disable parallel testing by commenting-out the <code class="language-plaintext highlighter-rouge">parallelize</code> line in <code class="language-plaintext highlighter-rouge">test_helper.rb</code>, as I found it was causing the tests to hang. I haven’t had a chance yet to look into the cause.)</p>

<h2 id="basic-setup">Basic Setup</h2>

<p>Overall, the setup for Jumpstart Pro is not so different than for any other Rails app, but the optional dependencies complicate things a little: If there is code that references a gem that isn’t installed, then typechecking will fail, even if it’s within a <code class="language-plaintext highlighter-rouge">defined?</code> check. To simplify things for this guide, we will open the Jumpstart configuration page and enable the following features:</p>

<ul>
  <li>Payment Processor: Stripe</li>
  <li>Background Queue: Sidekiq</li>
  <li>ActsAsTenant</li>
  <li>Facebook Omniauth Provider</li>
</ul>

<p>This will result in some additions to <code class="language-plaintext highlighter-rouge">Gemfile.lock</code> which you should commit.</p>

<p>Next, we’ll add the <code class="language-plaintext highlighter-rouge">sorbet-static-and-runtime</code> and <code class="language-plaintext highlighter-rouge">tapioca</code> gems to the <code class="language-plaintext highlighter-rouge">Gemfile</code>, run <code class="language-plaintext highlighter-rouge">bundle</code> then <code class="language-plaintext highlighter-rouge">bundle exec tapioca init</code>.</p>

<p>The <code class="language-plaintext highlighter-rouge">init</code> command can take a long time to run (10 minutes or more), and it may seem like it has frozen. Have patience!</p>

<p>You may be alarmed by the huge number of RBI files this creates, but you will very rarely need to interact with them.</p>

<p>After this is complete, we can commit everything. Let’s now run the typechecker:</p>

<div class="language-sh highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nv">$ </span>bundle <span class="nb">exec </span>srb tc
</code></pre></div></div>

<p>We should see about 20 errors. It’s common to encounter errors when setting up Sorbet initially, usually due to known limitations in Sorbet or Tapioca.</p>

<p>In the case of Jumpstart, several are due <a href="https://sorbet.org/docs/error-reference#5068">potentially ambiguous</a> definitions, which are easily fixed by using the full version of the definition. For example instead of:</p>

<div class="language-ruby highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">module</span> <span class="nn">Admin</span>
  <span class="k">class</span> <span class="nc">User::ImpersonatesController</span> <span class="o">&lt;</span> <span class="no">Admin</span><span class="o">::</span><span class="no">ApplicationController</span>
  <span class="k">end</span>
<span class="k">end</span>
</code></pre></div></div>
<p>we need to write:</p>
<div class="language-ruby highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="k">module</span> <span class="nn">Admin</span>
  <span class="k">module</span> <span class="nn">User</span>
    <span class="k">class</span> <span class="nc">ImpersonatesController</span> <span class="o">&lt;</span> <span class="no">Admin</span><span class="o">::</span><span class="no">ApplicationController</span>
    <span class="k">end</span>
  <span class="k">end</span>
<span class="k">end</span>
</code></pre></div></div>

<p>Other errors are because some parts of the gem are not required by default. We need to add an entry to Tapioca’s <code class="language-plaintext highlighter-rouge">require.rb</code>:</p>

<div class="language-yml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="c1"># sorbet/tapioca/require.rb</span>
<span class="s">require "administrate/base_dashboard"</span>
</code></pre></div></div>

<p>and then re-run <code class="language-plaintext highlighter-rouge">bundle exec tapioca gem administrate</code>.</p>

<p>After this there should be only handful of remaining errors, which are due to the Sorbet limitation that “include must only contain constant literals”. We can work around this by marking those calls as unsafe:</p>

<div class="language-ruby highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="no">T</span><span class="p">.</span><span class="nf">unsafe</span><span class="p">(</span><span class="nb">self</span><span class="p">).</span><span class="nf">include</span> <span class="no">Engine</span><span class="p">.</span><span class="nf">routes</span><span class="p">.</span><span class="nf">url_helpers</span>
</code></pre></div></div>

<p>At this point you can push to CI and everything should be green again. If you wish, you can merge the <code class="language-plaintext highlighter-rouge">sorbet</code> branch into <code class="language-plaintext highlighter-rouge">main</code> and continue the remaining work in other branches.</p>

<h2 id="clearing-the-todo-list">Clearing the TODO list.</h2>

<p>Although we are no longer seeing any typechecking errors, some things are being ignored because they are listed in <code class="language-plaintext highlighter-rouge">todo.rbi</code> which was generated by <code class="language-plaintext highlighter-rouge">sorbet init</code>. We should aim to eliminate these before continuing.</p>

<p>We intentionally never manually edit <code class="language-plaintext highlighter-rouge">todo.rbi</code> - we’ll make a change, and then regenerate it, to gradually reduce the number of entries.</p>

<p>Many of the remaining entries in <code class="language-plaintext highlighter-rouge">todo.rbi</code> are due to optional gems, where they are conditionally referenced in an initializer. We could just delete those, but that would make it a little tricker pulling in changes from upstream in Jumpstart Pro. The approach I suggest is using Ruby’s <code class="language-plaintext highlighter-rouge">__END__</code> keywords. It indicates that the code in the file has ended, and so Ruby (and Sorbet) will ignore it:</p>

<div class="language-ruby highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="cp">__END__

Bugsnag.configure do |config|
  config.api_key = Rails.application.credentials.dig(:bugsnag, :api_key)
end
</span></code></pre></div></div>

<p>Next, we have some entries in <code class="language-plaintext highlighter-rouge">todo.rbi</code> that relate to the Devise and Noticed gems. For gems that make use of metaprogramming, we often need to give Sorbet some help by adding <a href="https://sorbet.org/docs/rbi">shims</a>.</p>

<div class="language-ruby highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="c1"># sorbet/shims.rbi</span>
<span class="k">class</span> <span class="nc">Devise::OmniauthCallbacksController</span><span class="p">;</span> <span class="k">end</span>
<span class="k">class</span> <span class="nc">Devise::RegistrationsController</span><span class="p">;</span> <span class="k">end</span>
<span class="k">class</span> <span class="nc">Devise::SessionsController</span><span class="p">;</span> <span class="k">end</span>

<span class="k">class</span> <span class="nc">Noticed::NotificationChannel</span><span class="p">;</span> <span class="k">end</span>
</code></pre></div></div>

<p>For <code class="language-plaintext highlighter-rouge">Minitest::Mock</code> and <code class="language-plaintext highlighter-rouge">Sidekiq::Web</code>, we again need to add entries to <code class="language-plaintext highlighter-rouge">require.rb</code> then regenerate the RBIs.</p>

<div class="language-ruby highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="c1"># sorbet/tapioca/require.rb</span>
<span class="nb">require</span> <span class="s2">"minitest/mock"</span>
<span class="nb">require</span> <span class="s2">"sidekiq/web"</span>
</code></pre></div></div>

<p>At this point, there should be no more entries in <code class="language-plaintext highlighter-rouge">todo.rbi</code> and running <code class="language-plaintext highlighter-rouge">tapioca todo</code> will delete it.</p>

<h2 id="standard">Standard</h2>

<p>Although Jumpstart uses Standard rather than RuboCop, there are some useful cops in <code class="language-plaintext highlighter-rouge">rubocop-sorbet</code>, so we will add  that as a dependency.</p>

<p>Then in <code class="language-plaintext highlighter-rouge">.standard.yml</code>, we’ll use Standard’s <a href="https://blog.testdouble.com/posts/2023-01-19-super-standard-adding-gem-extensions-and-custom-rules/">extend_config</a> feature to reference a RuboCop Sorbet configuration file:</p>

<div class="language-yml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="c1"># .standard.yml</span>
<span class="na">extend_config</span><span class="pi">:</span>
  <span class="pi">-</span> <span class="s">.rubocop_sorbet.yml</span>
</code></pre></div></div>

<p>The config will look like this:</p>

<div class="language-yml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="c1"># .rubocop_sorbet.yml</span>
<span class="na">require</span><span class="pi">:</span> <span class="s">rubocop-sorbet</span>

<span class="na">AllCops</span><span class="pi">:</span>
  <span class="na">NewCops</span><span class="pi">:</span> <span class="s">disable</span>
  <span class="na">Exclude</span><span class="pi">:</span>
    <span class="pi">-</span> <span class="s">lib/jumpstart/test/dummy/**/*</span>
<span class="na">Sorbet/ConstantsFromStrings</span><span class="pi">:</span>
  <span class="na">Exclude</span><span class="pi">:</span>
    <span class="pi">-</span> <span class="s1">'</span><span class="s">app/models/connected_account.rb'</span>
</code></pre></div></div>

<p>We’ll ignore the Dummy app used by the internal jumpstart gem, since that should be treated as a separate application.</p>

<p>We also we need to disable the <code class="language-plaintext highlighter-rouge">ConstantsFromStrings</code> check for one file, due to Sorbet’s limitations for <code class="language-plaintext highlighter-rouge">const_get</code>.</p>

<p>With that done, we can now run <code class="language-plaintext highlighter-rouge">bundle exec standardrb --fix</code> which will add a <code class="language-plaintext highlighter-rouge">typed: false</code> entry to each file. This happens because rubocop-sorbet’s default configuration enables the <code class="language-plaintext highlighter-rouge">Sorbet/FalseSigil</code> cop, which ensures all files are at a strictness of a least <code class="language-plaintext highlighter-rouge">false</code>.</p>

<p>On its own that doesn’t do anything, but it prepares the way so that we can use Spoom.</p>

<h2 id="spoom">Spoom</h2>

<p>Spoom consists of several tools, one of which is the <code class="language-plaintext highlighter-rouge">bump</code> command:</p>

<div class="language-sh highlighter-rouge"><div class="highlight"><pre class="highlight"><code>bundle <span class="nb">exec </span>spoom bump
</code></pre></div></div>
<p>This helps us discover which files can be ‘bumped’ up a level of typing.</p>

<p>You should see that a large number are now marked as <code class="language-plaintext highlighter-rouge"># typed: true</code>, without us having to do any work.</p>

<h2 id="next-steps">Next Steps</h2>

<p>At this point, you can search for <code class="language-plaintext highlighter-rouge"># typed: false</code> in <code class="language-plaintext highlighter-rouge">*.rb</code> and you’ll see there are around 100 files remaining that aren’t yet typed. Resolving all those is outside the scope of this post, but you now have a strong starting point.</p>

<p>You’ll notice that we haven’t written any signatures yet. But even without those, we can start benefiting from Sorbet’s checks for things such as calls to non-existing methods, or unreachable code.</p>]]></content><author><name></name></author><summary type="html"><![CDATA[This post describes the process of setting up Sorbet and Tapioca for the Jumpstart Pro Rails template.]]></summary></entry><entry><title type="html">A GitHub Actions Rails CI Workflow in 5 lines</title><link href="http://www.andywaite.com/2022/04/15/reusable-github-actions-rails-workflow.html" rel="alternate" type="text/html" title="A GitHub Actions Rails CI Workflow in 5 lines" /><published>2022-04-15T00:00:00+00:00</published><updated>2022-04-15T00:00:00+00:00</updated><id>http://www.andywaite.com/2022/04/15/reusable-github-actions-rails-workflow</id><content type="html" xml:base="http://www.andywaite.com/2022/04/15/reusable-github-actions-rails-workflow.html"><![CDATA[<p>A few years ago, Matt Swanson wrote a <a href="https://boringrails.com/articles/building-a-rails-ci-pipeline-with-github-actions/">great post</a> on setting up Rails CI on GitHub Actions. It quickly became my go-to reference for setting up CI for new apps.</p>

<p>Over time, I made few updates and adjustments to it, so whenever I started a new project I would copy the config from one of my older projects.
But this meant each project gradually became inconsistent, and some got updated more than others.</p>

<p>I wanted to have one single base workflow for all my apps, so that if I made a change, all the apps could easily benefit from it.</p>

<h2 id="reusable-workflows">Reusable Workflows</h2>

<p>In November 2021, GitHub announced that <a href="https://github.blog/2021-11-29-github-actions-reusable-workflows-is-generally-available/">Reusable Workflows</a> was generally available.</p>

<p>Although GitHub Actions has supported composite actions for a long time, Reusable Workflows allows for a much more concise configuration, and the ability to reference a whole workflow from another repository, rather than having to build up each step individually.</p>

<p><a href="https://github.blog/2022-02-10-using-reusable-workflows-github-actions/">Read more about it on GitHub’s blog</a>.</p>

<h2 id="introducing-setup-rails">Introducing setup-rails</h2>

<p>Using the Reusable Workflows feature, I’ve created <strong><a href="https://github.com/andyw8/setup-rails">setup-rails</a></strong> for quickly and easily enabling CI for Rails apps.</p>

<p>By creating a single file in your repo, e.g. <code class="language-plaintext highlighter-rouge">.github/workflows/verify.yml</code>, with the contents below, you should have a working CI workflow which configures the database and runs your app’s tests:</p>

<div class="language-yaml highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="na">name</span><span class="pi">:</span> <span class="s">Verify</span>
<span class="na">on</span><span class="pi">:</span> <span class="pi">[</span><span class="nv">push</span><span class="pi">]</span>

<span class="na">jobs</span><span class="pi">:</span>
  <span class="na">verify</span><span class="pi">:</span>
    <span class="na">uses</span><span class="pi">:</span> <span class="s">andyw8/setup-rails/.github/workflows/verify.yml@v1</span>
</code></pre></div></div>

<p>You can take a look at <a href="https://github.com/andyw8/setup-rails-example-app">this example app</a> to see it in action.</p>

<p>The first time you run the workflow may be slow, but subsequent runs should be much faster once the dependencies are cached.</p>

<p>I’ve also shared a <a href="https://railsbytes.com/templates/VMys8A">Railsbyte</a> so that you can set this up with one command:</p>

<p><code class="language-plaintext highlighter-rouge">rails app:template LOCATION="https://railsbytes.com/script/VMys8A"</code></p>

<h2 id="principles-and-configuration">Principles and Configuration</h2>

<p>I designed <code class="language-plaintext highlighter-rouge">setup-rails</code> so it should work at a basic level with no configuration needed for most apps.</p>

<p>There are a few options you can enable depending on your app, such as RuboCop, Bundler Audit and RSpec - see the <a href="https://github.com/andyw8/setup-rails">README</a> for details.</p>

<p>Currently only Postgres is supported but I’d like to expand to cover at least MySQL.</p>

<h2 id="enhancements">Enhancements</h2>

<p>Building upon Matt’s great starting point, I made a few updates:</p>

<ul>
  <li>Uses the latest versions of <code class="language-plaintext highlighter-rouge">setup-node</code> and <code class="language-plaintext highlighter-rouge">setup-ruby</code></li>
  <li>Adds support for <code class="language-plaintext highlighter-rouge">rails test</code> (e.g. Minitest) as well as RSpec</li>
  <li><a href="https://github.com/andyw8/setup-rails/blob/main/.github/dependabot.yml">Enabled Dependabot</a> for updates of the actions that <code class="language-plaintext highlighter-rouge">setup-rails</code> depends on</li>
  <li>Uses <code class="language-plaintext highlighter-rouge">setup-node</code>’s JavaScript caching rather than a custom approach</li>
  <li>Skips <code class="language-plaintext highlighter-rouge">development</code> gems when running Bundler to avoid unnecessary work.</li>
</ul>

<h2 id="get-involved">Get Involved</h2>

<p>I’m already using this on most of my apps, but I’d love to get wider feedback.</p>

<p>Please try <a href="https://github.com/andyw8/setup-rails">setup-rails</a> on your app and let me know how it works for you. Issues and pull requests are welcome!</p>]]></content><author><name></name></author><summary type="html"><![CDATA[A few years ago, Matt Swanson wrote a great post on setting up Rails CI on GitHub Actions. It quickly became my go-to reference for setting up CI for new apps.]]></summary></entry><entry><title type="html">My Ruby Kata Template</title><link href="http://www.andywaite.com/2022/04/09/ruby-kata-template.html" rel="alternate" type="text/html" title="My Ruby Kata Template" /><published>2022-04-09T00:00:00+00:00</published><updated>2022-04-09T00:00:00+00:00</updated><id>http://www.andywaite.com/2022/04/09/ruby-kata-template</id><content type="html" xml:base="http://www.andywaite.com/2022/04/09/ruby-kata-template.html"><![CDATA[<p>Recently I’ve been aiming to do more <a href="http://codekata.com/">katas</a>, both in my personal time, and at <a href="https://shopify.engineering/">work</a> in our <a href="https://github.com/97-things/97-things-every-programmer-should-know/blob/master/en/thing_22/README.md">Deliberate Practice</a> group.</p>

<p>I noticed that whenever I was starting on a new kata, I was doing the same basic setup repeatedly before being able to write a first test. I also felt I was missing some of the configuration that my other ‘real’ projects benefited from.</p>

<p>This led me to create <a href="https://github.com/andyw8/ruby-kata-template">ruby-kata-template</a>. By clicking on <strong>Use this template</strong>, I get a new blank project in seconds, configured to my preferences.</p>

<p>I don’t expect my preferences to match everyone else’s, so I encourage you to fork it and customize to your own ideal template.</p>

<h2 id="features">Features</h2>

<h3 id="starting-point">Starting Point</h3>

<p>There is an empty Project (<code class="language-plaintext highlighter-rouge">project.rb</code>) and a corresponding test (<code class="language-plaintext highlighter-rouge">project_test.rb</code>). I expect the first step in many katas will be to rename these.</p>

<h3 id="directory-structure">Directory Structure</h3>

<p>I’ve followed the standard Ruby convention of the implementation being in <code class="language-plaintext highlighter-rouge">lib/</code> and the tests in <code class="language-plaintext highlighter-rouge">test/</code></p>

<h3 id="minitest">Minitest</h3>

<p>Although Minitest is already provided as a Bundled gem with Ruby, it’s included in the <code class="language-plaintext highlighter-rouge">Gemfile</code> to ensure we’re on the latest version. (I’ve used RSpec extensively in the past, but my current preference is Minitest).</p>

<h3 id="activesupporttestcase">ActiveSupport::TestCase</h3>

<p><code class="language-plaintext highlighter-rouge">ActiveSupport::TestCase</code> is part of Rails but here we are using it independently. It allows you to write ‘declarative’ tests, e.g. <code class="language-plaintext highlighter-rouge">test "it works" do...</code> rather than <code class="language-plaintext highlighter-rouge">def test_it_works</code>, which I feel is more readable.</p>

<h3 id="rake-task">Rake Task</h3>

<p>It’s common on Ruby apps to have <code class="language-plaintext highlighter-rouge">rake</code> or <code class="language-plaintext highlighter-rouge">rake test</code>, so we provide that. It has support for <a href="https://minitest.rubystyle.guide/#file-naming">both MiniTest naming conventions</a> (<code class="language-plaintext highlighter-rouge">test_*.rb</code> and <code class="language-plaintext highlighter-rouge">*_test.rb</code>)</p>

<h3 id="standard">Standard</h3>

<p><a href="https://github.com/testdouble/standard">Standard</a> is an opinionated RuboCop configuration.</p>

<p>For me, the real value of Standard (or RuboCop) is only apparent when you have two things configured in your editor:</p>
<ul>
  <li>Immediate feedback (your editor highlights problems as you code)</li>
  <li>Auto-formatting (you can fix issues with one single shortcut, or automatically when the file is saved).</li>
</ul>

<p>There are various ways to set up this, but the template uses <code class="language-plaintext highlighter-rouge">rubocop-lsp</code>.</p>

<h3 id="rubocop-lsp">rubocop-lsp</h3>

<p><a href="https://rubygems.org/gems/rubocop-lsp">rubocop-lsp</a> is a gem which implements the <a href="https://en.wikipedia.org/wiki/Language_Server_Protocol">Language Server Protocol</a>. It allows for a close integration between your editor with RuboCop. It avoids the overhead of starting RuboCop, meaning linting or auto-correction is near-instant.</p>

<p>To use it, you’ll also need an plugin or extension for your editor. The template is set up to recommend the VS Code <a href="https://marketplace.visualstudio.com/items?itemName=Shopify.rubocop-lsp">Shopify.rubocop-lsp</a> extension.</p>

<h2 id="solargraph">Solargraph</h2>

<p>Solargraph adds IDE-like experience for your editor. It provides helpful features such as a content-aware autocompletion, and documentation for the Ruby language.</p>

<p>However, I often run into problems with it, so I was on the fence about including it.</p>

<p>It’s not as powerful as <a href="https://sorbet.org/">Sorbet</a>, so it’s unable to infer types unless they are a Ruby primitive (String, Array, etc.)</p>

<p><img src="images/solargraph-example.png" alt="Solargraph example" /></p>

<h3 id="and-more">And more</h3>

<p>Take a look at the <a href="https://github.com/andyw8/ruby-kata-template#readme">README</a> to learn what else is included.</p>]]></content><author><name></name></author><summary type="html"><![CDATA[Recently I’ve been aiming to do more katas, both in my personal time, and at work in our Deliberate Practice group.]]></summary></entry><entry><title type="html">Defining your team’s policy for broken builds</title><link href="http://www.andywaite.com/2020/03/16/define-your-teams-broken-build-policy.html" rel="alternate" type="text/html" title="Defining your team’s policy for broken builds" /><published>2020-03-16T00:00:00+00:00</published><updated>2020-03-16T00:00:00+00:00</updated><id>http://www.andywaite.com/2020/03/16/define-your-teams-broken-build-policy</id><content type="html" xml:base="http://www.andywaite.com/2020/03/16/define-your-teams-broken-build-policy.html"><![CDATA[<p>To deliver working software incrementally, and at a sustainable pace, it’s critical to keep the master build passing at all times.</p>

<p>A failing build is demoralizing and disruptive for the team.
Developers and testers will lose confidence in the correctness of the system.
They may be unable to know if a failing test was due to their change, or to something else.</p>

<p>Keeping the master build passing should take priority over almost everything else.
The whole team should feel responsible for it, and when the build fails, the whole team should be alerted.
It shouldn’t be left to a ‘devops’ team, or only to senior developers.
One option is to configure your CI to post notifications to your team’s Slack channel for high visibility.</p>

<p>We can adopt several practices to help ensure master stays passing:</p>

<ul>
  <li>Performing code reviews to detect potentially problematic tests</li>
  <li>Running linters to catch common problem areas, such as rubocop-rspec</li>
  <li>Using features such as <a href="https://developer.github.com/v3/checks/">GitHub Checks</a> to enforce a passing build before the branch can be merged into master.</li>
</ul>

<p>But even with these practices, things can still go wrong:</p>

<ul>
  <li>We can have intermittent failures due to factors such as time of day or concurrency.</li>
  <li>We can have a <a href="https://www.martinfowler.com/bliki/SemanticConflict.html">semantic conflict</a>, where behaviour is correct on individual branches but incorrect when they’re combined.</li>
  <li>We can have infrastructure failures unrelated to the code.</li>
</ul>

<p>It’s important to establish a clear process for what should be done when the master build fails.
The details of this should be discussed and agreed by your team, but I’ll discuss one starting point.</p>

<p>In most cases, the most recent merge will be the one that broke the build.
If the author of the most recent merge hasn’t reacted to the failure, send a gentle nudge.</p>

<p>The first thing the author should do is pull the latest master, and check if the test passes locally.
If it fails, that gives a good starting point. If it passes, we’ll have to broaden the investigation.</p>

<p>While this in progress, there are two key things to keep in mind:</p>

<ul>
  <li>Getting the build back to passing as soon as possible</li>
  <li>Keeping the team informed, and sharing an ETA if feasible</li>
</ul>

<p>If the team isn’t aware of work going on, a developer might assume that a failure was due to their change.
Or another developer may start investigating the failure, unaware that someone else is already on it.
Both could result in wasted time.</p>

<p>The next step is more nuanced. It may need discussion with the team, and could depend on the nature of your project:</p>

<ul>
  <li>Should you revert?</li>
  <li>Should you temporarily disable the test?</li>
  <li>Should you delete a flawed test?</li>
</ul>

<p>Have a clear written policy for this is useful, for example in your wiki or README.</p>

<p>If the fix is going to take some time to resolve, you should aim to give updates at least every hour or so.</p>

<p>Once the problem is resolved, take some time to reflect.
Was there a particular practice which caused this? Could you make some change to improve things?
There’s almost always some learning opportunity.</p>]]></content><author><name></name></author><summary type="html"><![CDATA[To deliver working software incrementally, and at a sustainable pace, it’s critical to keep the master build passing at all times.]]></summary></entry></feed>